The Promise of the Clean Slate
For decades, the path to homeownership in the United States was haunted by the legacy of redlining.
Throughout the mid-20th century, loan officers sat in bank branches with literal red pens, tracing boundaries around minority neighborhoods on municipal maps. Anyone living inside those red ink lines was automatically denied a mortgage, regardless of their individual income, creditworthiness, or personal character.
When the financial technology (fintech) revolution accelerated in the mid-2010s, Silicon Valley promised an objective technological cure.
The sales pitch was clean and compelling: remove human beings from the decision loop. Human loan officers harbor subconscious biases, prejudices, and bad days. An algorithm, by contrast, has no skin color, no ethnic prejudice, and no hometown nostalgia. An algorithm looks only at the cold, hard numbers: income, debt-to-income ratio, payment history, and credit scores.
Mathematics, tech executives proclaimed, cannot be racist.
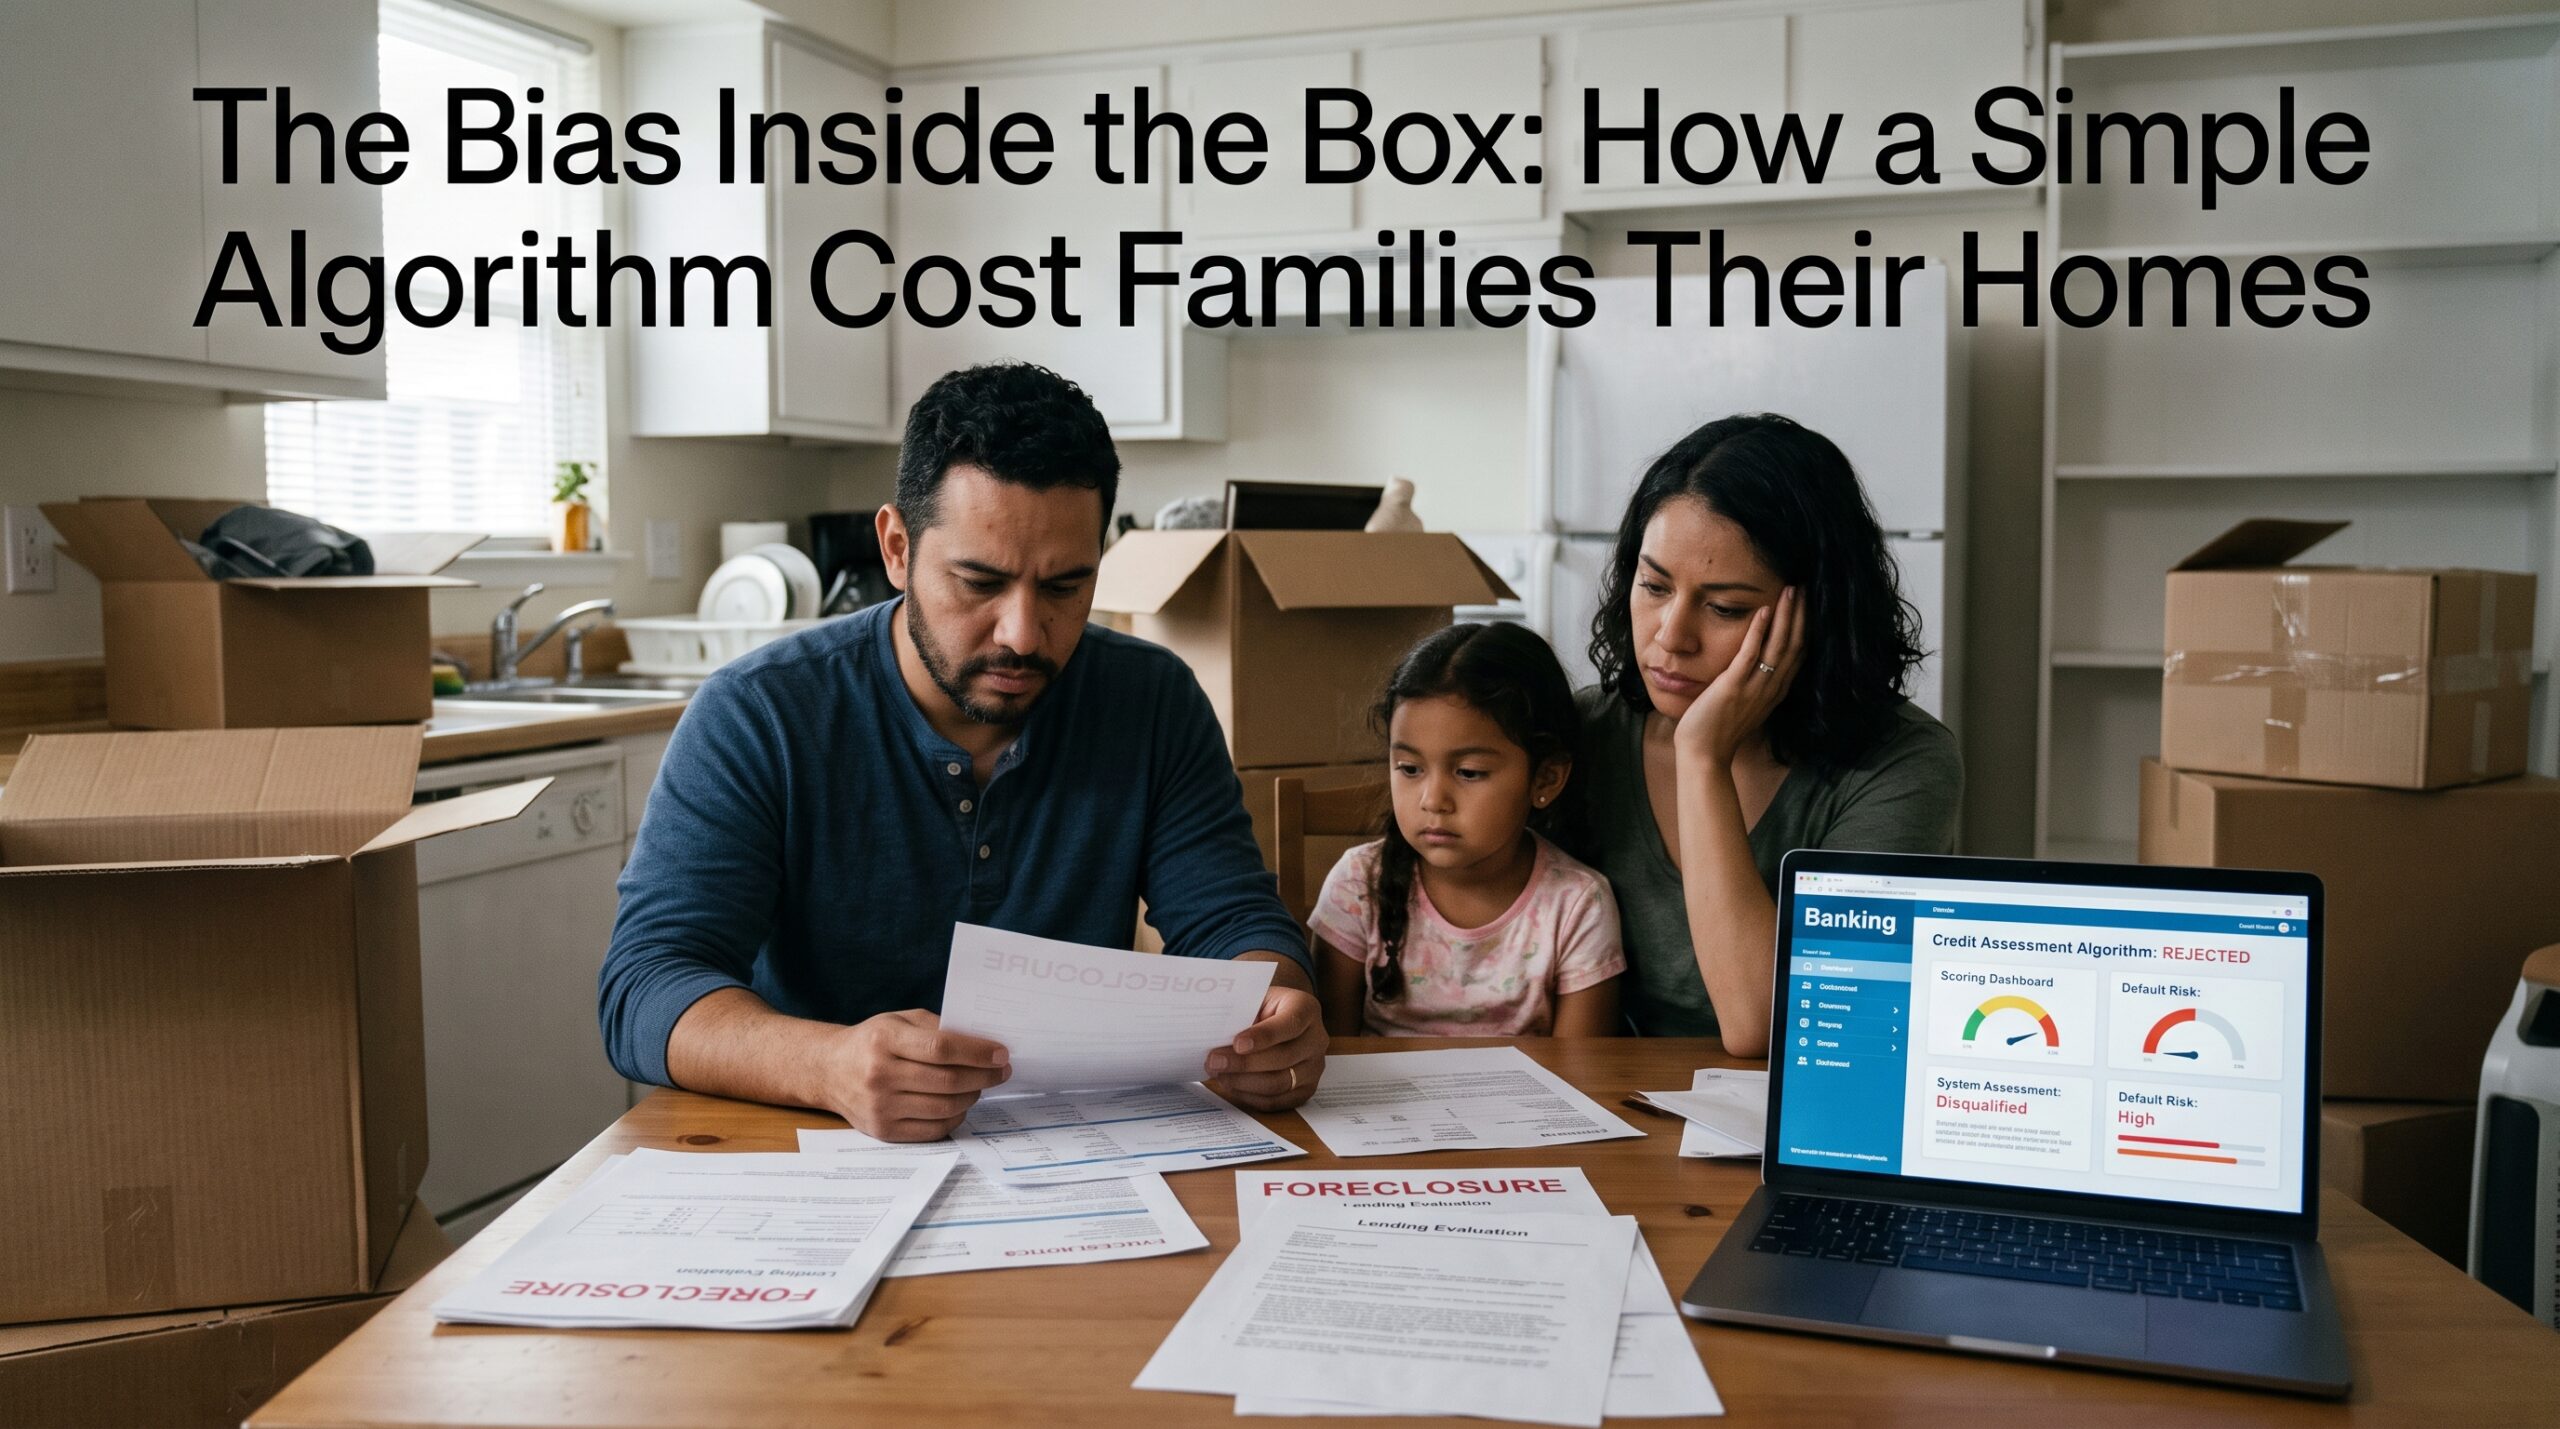
Yet between 2018 and 2021, massive statistical investigations by organizations like The Markup and the Associated Press exposed an uncomfortable reality: when lenders handed loan underwriting over to automated machine learning models, minority applicants were still significantly more likely to be rejected than their white peers with identical financial profiles.
The bias hadn’t been eliminated. It had simply been laundered through code.
The Anatomy of an Automated Underwriting System
To understand how clean math creates discriminatory outcomes, one must dissect how a modern automated underwriting system (AUS) operates.
A bank does not write an explicit code statement saying: IF applicant == minority THEN reject. Indeed, the Fair Housing Act and the Equal Credit Opportunity Act make it illegal to include race, gender, or religion as features in any credit model.
Instead, companies train supervised learning models—such as XGBoost, Random Forests, or deep neural networks—on decades of historical mortgage outcomes. The model’s objective function is mathematically straightforward: maximize profit while minimizing the probability of default.
The model is fed millions of historical loan files:
- Debt ratios
- Employment tenure
- Credit scores
- Down payment percentages
- Zip codes
- Transaction histories
- Property assessment values
The algorithm searches for complex non-linear correlations across these thousands of variables to predict a single scalar value: the likelihood that this applicant will fail to make payments over a 30-year timeframe.
The Ghost of Redlining: The Proxy Problem
Machine learning models do not understand social history, systemic inequality, or justice; they understand statistical correlation. And because our present world is built directly upon historical systems, the algorithm quickly discovers proxy variables.
A proxy variable is a piece of innocent-looking data that correlates heavily with a protected characteristic.
Neutral Data Input (Feature) ────────► Hidden Sociological Correlation
————————————————————————–
Zip Code ────────► Historical Neighborhood Segregation
FICO Credit Score ────────► Intergenerational Wealth Disparities
Length of Credit History ────────► Access to Legacy Banking Systems
Frequency of Small Bank Fees ────────► Banking Deserts / Low Branch Density
Even if you strip race completely from the training dataset, an advanced gradient-boosted tree doesn’t need a column labeled “Race.” By combining an applicant’s five-digit zip code, their employer’s industry code, their educational institution, and the geographic location of their recurring debit purchases, the algorithm reconstructs demographic profiles with over 90% statistical confidence.
The machine simply reinvented the red pen—not out of malice, but because historical data taught it that individuals living in those geographic coordinates historically held lower intergenerational wealth and higher default risks.
The Markup Investigation: The Real Human Cost
In 2021, The Markup completed a monumental statistical analysis of more than two million conventional mortgage applications submitted in 2019, using data made public under the Home Mortgage Disclosure Act (HMDA).
Their data scientists controlled for all publicly available financial factors:
- Income levels
- Debt-to-income ratios
- Combined loan-to-value ratios
- Loan amounts
- Property values
The findings were devastating:
- Black applicants were 80% more likely to be rejected for a mortgage than white applicants with comparable financial credentials.
- Latino applicants were 40% more likely to be rejected.
- Asian/Pacific Islander applicants were 87% more likely to be rejected.
In city after city, families with stable incomes, spotless rental histories, and zero debt walked away with automated rejection letters generated by black-box underwriting engines.
When applicants asked their loan officers why their application had failed, the loan officers frequently couldn’t answer. The decisions were handled by third-party proprietary software systems whose internal multi-layer decision boundaries were inaccessible to the branch employees themselves.
Why “De-biasing” Is an Engineering Minefield
Why can’t data engineers simply fix the math? Because in automated systems, fairness is not a simple toggle switch; it is a mathematical trade-off.
In AI ethics and algorithmic fairness, computer scientists face the Impossibility Theorem of Machine Fairness (proven mathematically by Kleinberg, Mullainathan, and Raghavan in 2016). The theorem proves that it is mathematically impossible for an algorithm to satisfy three common definitions of fairness simultaneously when base rates of historical outcomes differ across groups:
- Statistical Parity: Approving equal percentages of applicants across all demographic groups.
- Predictive Parity: Ensuring that a given risk score (e.g., 720) corresponds to the exact same probability of default, regardless of group identity.
- Equal Opportunity (Calibration): Ensuring that qualified borrowers who would successfully repay their loan have the exact same likelihood of being approved, regardless of group identity.
You can tune a model to satisfy one or two of these constraints, but you must mathematically sacrifice the third. Lenders, prioritizing default risk and balance-sheet safety under regulatory capital requirements, almost universally choose standard predictive parity. In doing so, they inevitably preserve disparate rejection rates for historically disadvantaged populations.
Beyond the Black Box
The crisis of automated mortgage lending reveals the foundational danger of the 21st-century algorithmic shift: the illusion of mathematical neutrality.
When a human loan officer denies someone a mortgage due to prejudice, they can be investigated, sued, and held legally accountable. But when an algorithm denies that same family their home, the rejection is cloaked in the untouchable authority of statistical objectivity.
Software systems do not inhabit an abstract world of pure logic. They are trained on our history, deployed in our present, and mirror our flaws.
If we feed an artificial intelligence historical data generated by an unequal society, the machine will not magically fix that inequality. It will systematically codify it, automate it, and scale it at the speed of light. True algorithmic intelligence requires that we stop asking our code to blindly mimic the historical past, and start engineering constraints that actively reflect the future we wish to build.